Many organisations back up their systems and data every day. That offers reassurance. The backup software reports that the job has completed successfully, the files have been stored and no errors have been reported.
But what happens if a critical system becomes unavailable tomorrow? Can you actually restore your data? How long will it take before employees can work again? And who decides which systems need to be recovered first? Those are different questions from whether a backup has succeeded.
A successful backup does not automatically mean your organisation can recover successfully.
Why this matters
IT systems are closely intertwined with day-to-day business operations. Employees depend on applications, files and communication tools that need to remain available. Customers expect orders to be processed, deliveries to continue and commitments to be met. When a system fails, the problem quickly extends beyond technology.
A manufacturer, for example, may be unable to process orders because its ERP system is unavailable. A trading company may be unable to prepare deliveries. Employees may be unable to continue working because files or applications cannot be accessed. The impact depends not only on the incident itself, but above all on how long it takes to restore business operations. That is why a sound recovery plan starts with the organisation, not the backup software.
Two questions that shape your recovery strategy
Two questions are particularly important when defining a recovery strategy.
1. How much data can you afford to lose?
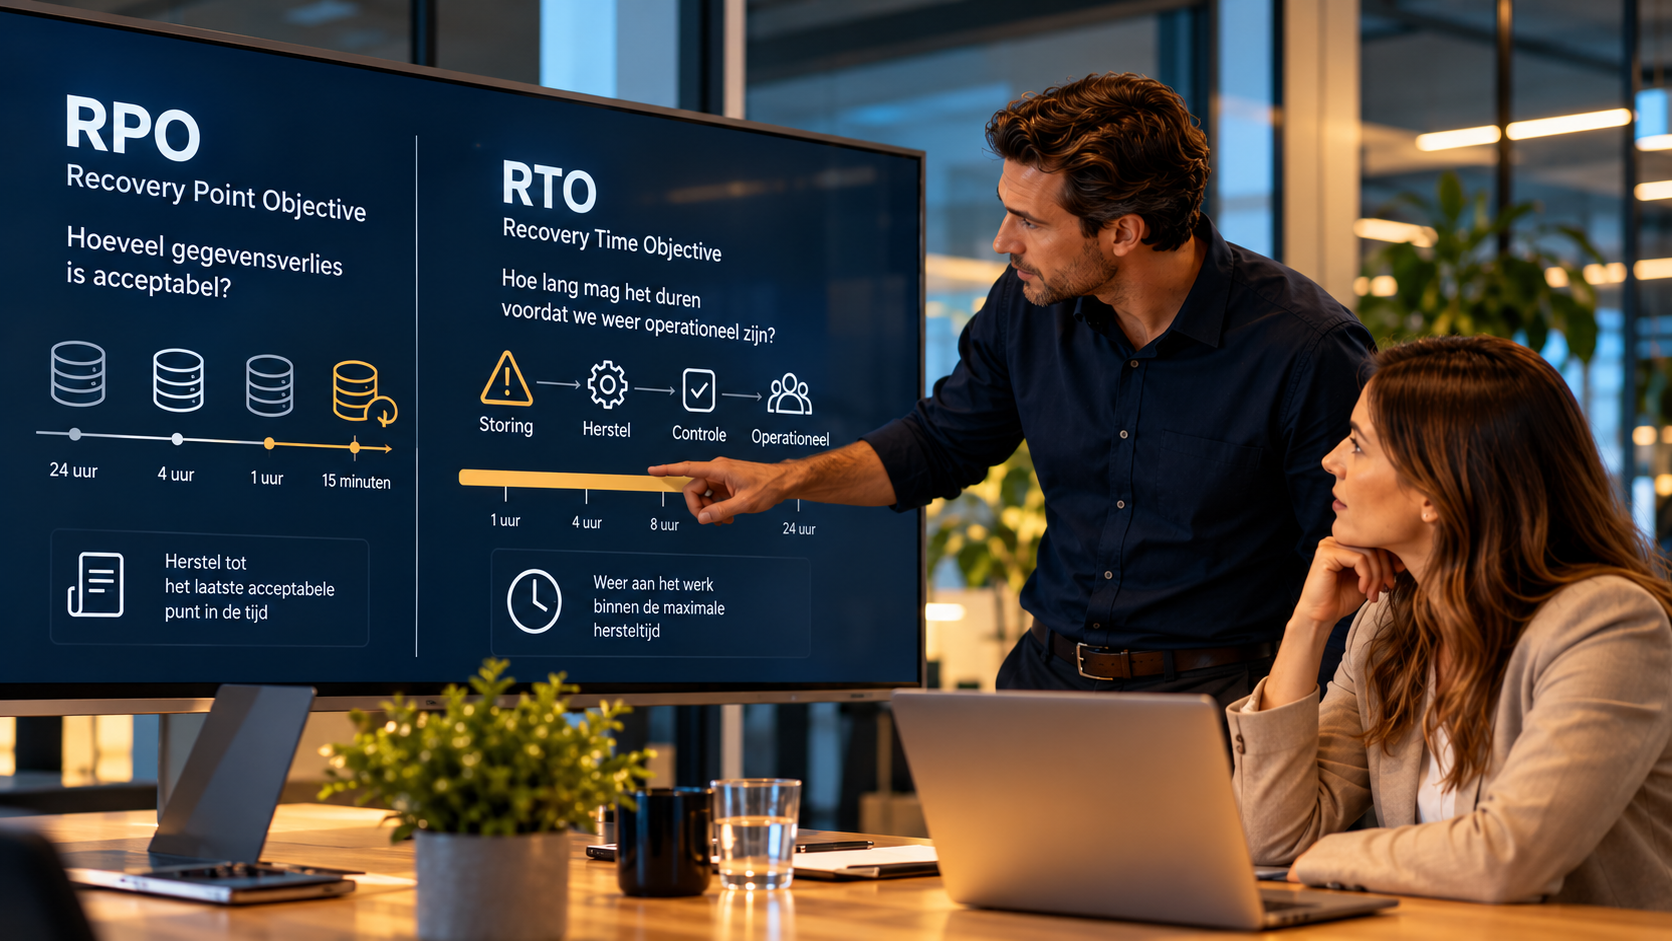
Imagine a system fails at 3 p.m. and the latest usable backup was made at midnight. That could mean all changes made during the working day need to be entered again, or are permanently lost. For some systems, that would be inconvenient but manageable. For other processes, the consequences could be substantial. Consider order processing, financial transactions, production data or changes to customer records. The maximum amount of data loss an organisation considers acceptable is commonly called the Recovery Point Objective (RPO).
An RPO of four hours means the recovery arrangements should be designed to limit the loss of data changes to no more than four hours. But only the organisation itself can decide whether four hours is acceptable.
2. How long can a system remain unavailable?
The second question is how long a system can be unavailable before it must be usable again. Restoring a backup may take minutes, but it can also take many hours or longer. This depends on factors such as data volumes, available infrastructure and dependencies between systems. The maximum acceptable recovery time is known as the Recovery Time Objective (RTO). An RTO of four hours means the recovery process should be designed to resume the relevant service within four hours.
That is not the same as a guarantee that recovery will succeed within that time under all circumstances. It requires appropriate provisions, clear agreements and, above all, demonstrably tested recovery procedures.
A QUESTION WORTH ASKING
If your most important business application were unavailable tomorrow morning, how many hours could your organisation continue before the consequences became unacceptable?
Recovery involves more than restoring files
Recovery is often associated with restoring files or a virtual server. In reality, a business application is rarely a completely self-contained system. An application may depend on a database, an identity service, network connections, storage, certificates or services provided by external suppliers. If one of these elements is missing, the application may have been technically restored while employees still cannot use it.
Consider an ERP environment. Restoring the application server is of little use if the associated database is unavailable. And if users cannot sign in, the environment remains practically unusable. An effective recovery strategy therefore considers the entire chain:
- Which business processes must resume first?
- Which applications support those processes?
- Which systems and external services do those applications depend on?
- In what order should components be restored?
- Which employees and suppliers need to be involved?
- How will we verify that the restored environment actually works?
It is precisely these dependencies that determine whether a recovery plan works in practice.
Four steps towards demonstrable recovery
Prioritise
the organisation decides
Identify critical business processes and define acceptable data loss (RPO) and maximum recovery time (RTO) for each process. Assign an owner authorised to approve recovery priorities and temporary ways of working.
Prepare
IT and suppliers put arrangements in place
Translate the objectives into protected backups, available recovery resources and a workable recovery sequence. Document dependencies, required access, contacts and agreements between suppliers.
Recover
the recovery coordinator leads
Have the parties involved work together according to the plan and recover the required chain of systems. Track time and decision points; the organisation decides when temporary measures or different priorities are needed.
Verify
users and IT check
Test whether data is usable and employees can resume the business process. Measure data loss and recovery time, compare them with RPO and RTO, and document improvements and a follow-up test.
The organisation defines what recovery must achieve; IT and suppliers make it workable. A functioning application is only sufficient when the associated business process is usable again.
An untested backup remains an assumption
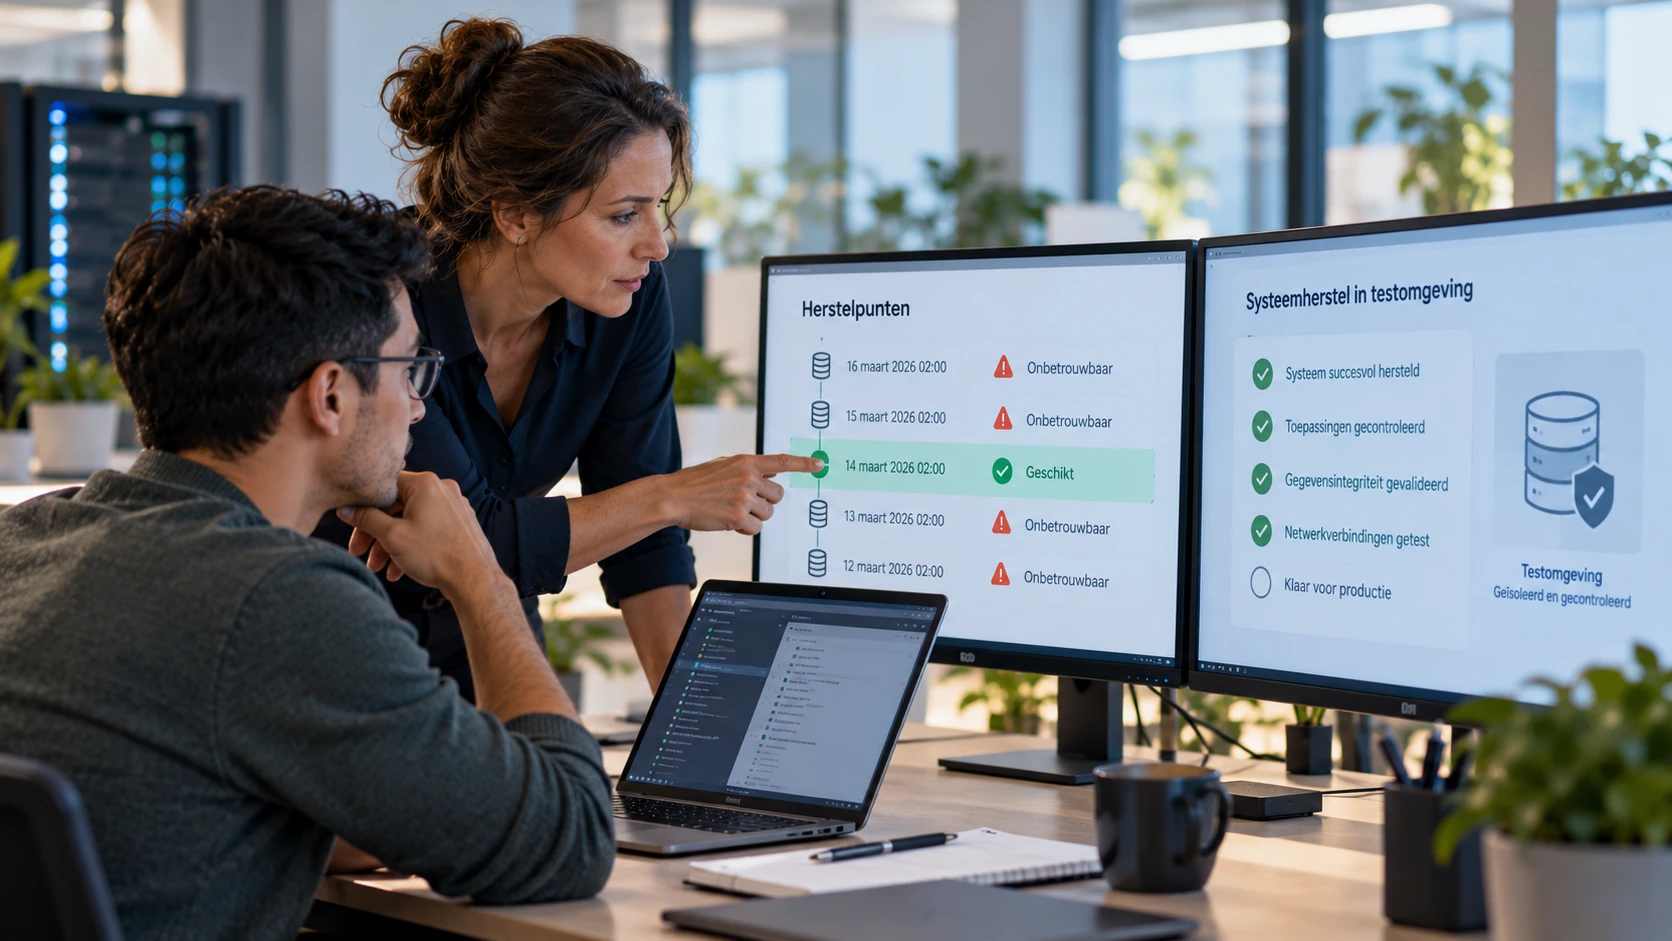
Backup software can generally establish whether data has been stored according to the configured procedure. However, that does not tell you everything about whether the data is usable. Files may have been copied correctly while an application fails to start after recovery. A database may be restored but no longer work properly with other parts of the environment. Recovery may also turn out to take much longer than expected. That is why regular testing is essential.
What should you test?
Not every test needs to be a full-scale disaster recovery exercise involving the entire organisation. A practical approach can include several levels:
- File recovery: check whether individual files can be restored correctly.
- System recovery: restore a server or workstation in a suitable test environment.
- Application recovery: verify that an application actually works, including its required data.
- End-to-end recovery: test whether interconnected systems and dependencies can be restored in the correct order.
- Business process recovery: ask users to verify that they can genuinely resume their work after recovery.
The results reveal where assumptions do not match reality. A recovery test is therefore not just a technical check; it is also a way to assess business risks in concrete terms.
Illustrative example
ERP recovery at a manufacturer
Situation. In a recovery test, a manufacturer simulates its ERP system becoming unavailable at 09:00. Order processing and production planning stop. The organisation has set an RPO of one hour and an RTO of four hours for this process.
- Approach
The recovery coordinator aligns the work of the IT service provider and the ERP supplier. They check the usable recovery point and restore the required network and identity services, database, application and integrations in the documented order. Employees temporarily record new orders using an agreed contingency procedure.
- Verification
In an isolated test environment, users check sign-in, existing orders, planning and an entire order processing workflow. The usable recovery point is 08:30: thirty minutes of data changes are missing. At 12:15, the tested process is usable again: three hours and fifteen minutes after the simulated outage. Both results are within the agreed objectives.
- Resumption
The process owner assesses whether the process works sufficiently and which checks are required before release. The team also rehearses the controlled entry of temporarily recorded orders, prevents duplicate entries and documents improvements and a follow-up test.
Key lesson: restoring an ERP server does not yet demonstrate business continuity. Verifying the entire chain, measuring results against RPO and RTO, and resuming work make recovery demonstrable. This test result is not a guarantee for every incident.
This is a fictional scenario for illustration, not a customer case or a description of results achieved by Malenco. The times and objectives were chosen solely for this example.
What if the backup itself is compromised?
During a serious security incident, such as a ransomware attack, the production environment may not be the only target. Backup systems may be targeted as well. If backups are accessible using the same administrator accounts, or are insufficiently isolated from the production environment, an attacker may also be able to delete or encrypt recovery data. A dependable backup strategy must therefore address the security of the backups themselves. Important measures include:
- Separate access to and administration of backup systems.
- Restricted administrator privileges and strong authentication.
- Backups that cannot easily be modified or deleted.
- An appropriate combination of local and off-site storage.
- Monitoring of backup results and anomalies.
- Periodic checks of the availability and integrity of recovery data.
The measures required depend on the risks, the design of the IT environment and the organisation's business continuity requirements. The objective is not to create as many backups as possible, but to have confidence that a usable recovery option will still exist after an incident.
Who is responsible when recovery is needed?
In many organisations, several parties are involved in the IT environment. One supplier manages the infrastructure, another supports the business application and a third provides the backup service. As long as everything works, that division of responsibilities need not be a problem. But when an incident occurs, an important question arises: who coordinates the response? Who decides which systems should be restored first? Who coordinates work between suppliers? And who determines whether business operations have been restored sufficiently?
Without clear agreements, valuable time can be lost even when every party performs its own tasks well. A recovery plan should therefore contain more than technical steps. It should also define responsibilities, contact details, escalation arrangements and decision points. Responsibility for business continuity cannot be transferred entirely to backup software or an IT supplier. The organisation itself must decide which consequences are acceptable and what its recovery priorities should be.
From a backup strategy to demonstrable recoverability
An organisation seeking greater control over its recovery capabilities does not necessarily need to start a major project immediately. It starts with understanding the situation. Which systems are genuinely critical? What happens if those systems fail? Which backups are available, and when was recovery last tested successfully? The technical arrangements and recovery procedures can then be assessed against the organisation's requirements. This leads to a practical approach:
- Identify critical business processes and their dependencies.
- Define acceptable data loss and recovery time for each process.
- Check whether the existing backup arrangements meet those requirements.
- Document recovery priorities and responsibilities.
- Test recovery under realistic conditions.
- Use the test results to improve systems and procedures.
A recovery plan is not a one-off document. Applications change, data volumes grow, employees move on and suppliers adapt their services. Recovery arrangements and agreements must therefore be reviewed periodically.
The question is not whether you have a backup
A backup is a necessary provision, but it is not proof of business continuity in itself. Its real value becomes clear only when systems fail and the organisation has to rely on its recovery capabilities. At that point, what matters is not only whether the data still exists, but whether the right systems, people and procedures are available to resume business operations. A dependable recovery strategy therefore connects technology with business processes, risks and responsibilities. The most important question is not whether we make backups, but whether we know how, and how quickly, we can get back to work.