When a business-critical IT system fails, the clock starts ticking. Employees cannot continue working, production processes come to a halt and customers may have to wait. An organisation may have reliable backups and a sound recovery plan, yet still discover that restoring all the necessary systems takes far longer than its business operations can tolerate.
For some systems, recovery within one working day is acceptable. For others, an interruption of just a few hours can have significant consequences. In these situations, accelerated recovery can help: additional technical provisions and recovery capabilities set up in advance shorten the time between a serious disruption and the resumption of work.
But recovering faster is not solely a technical matter. It requires an understanding of the business processes that depend on IT, the systems those processes need and the risks that arise if a recovery provision itself proves insufficiently reliable.
Why standard recovery is sometimes not fast enough
A traditional recovery procedure generally starts with making replacement infrastructure available, restoring systems and data, and checking whether applications are working again. Depending on the size and complexity of the environment, this can take anything from a few hours to several days. Recovery time can increase considerably, particularly when entire servers need to be rebuilt, large volumes of data need to be restored or external suppliers are required.
This need not be a problem as long as the recovery time is proportionate to the consequences an organisation can bear. An archive system that is temporarily unavailable, for example, calls for a different approach from an ERP system used to manage production orders, stock movements and deliveries. The same applies to systems needed for customer contact, logistics or access to business applications.
Assessing the need for accelerated recovery therefore starts with business operations. Which processes come to a halt when a system is unavailable? What are the financial, operational or contractual consequences? And how long can the business manage the situation before the damage becomes unacceptable?
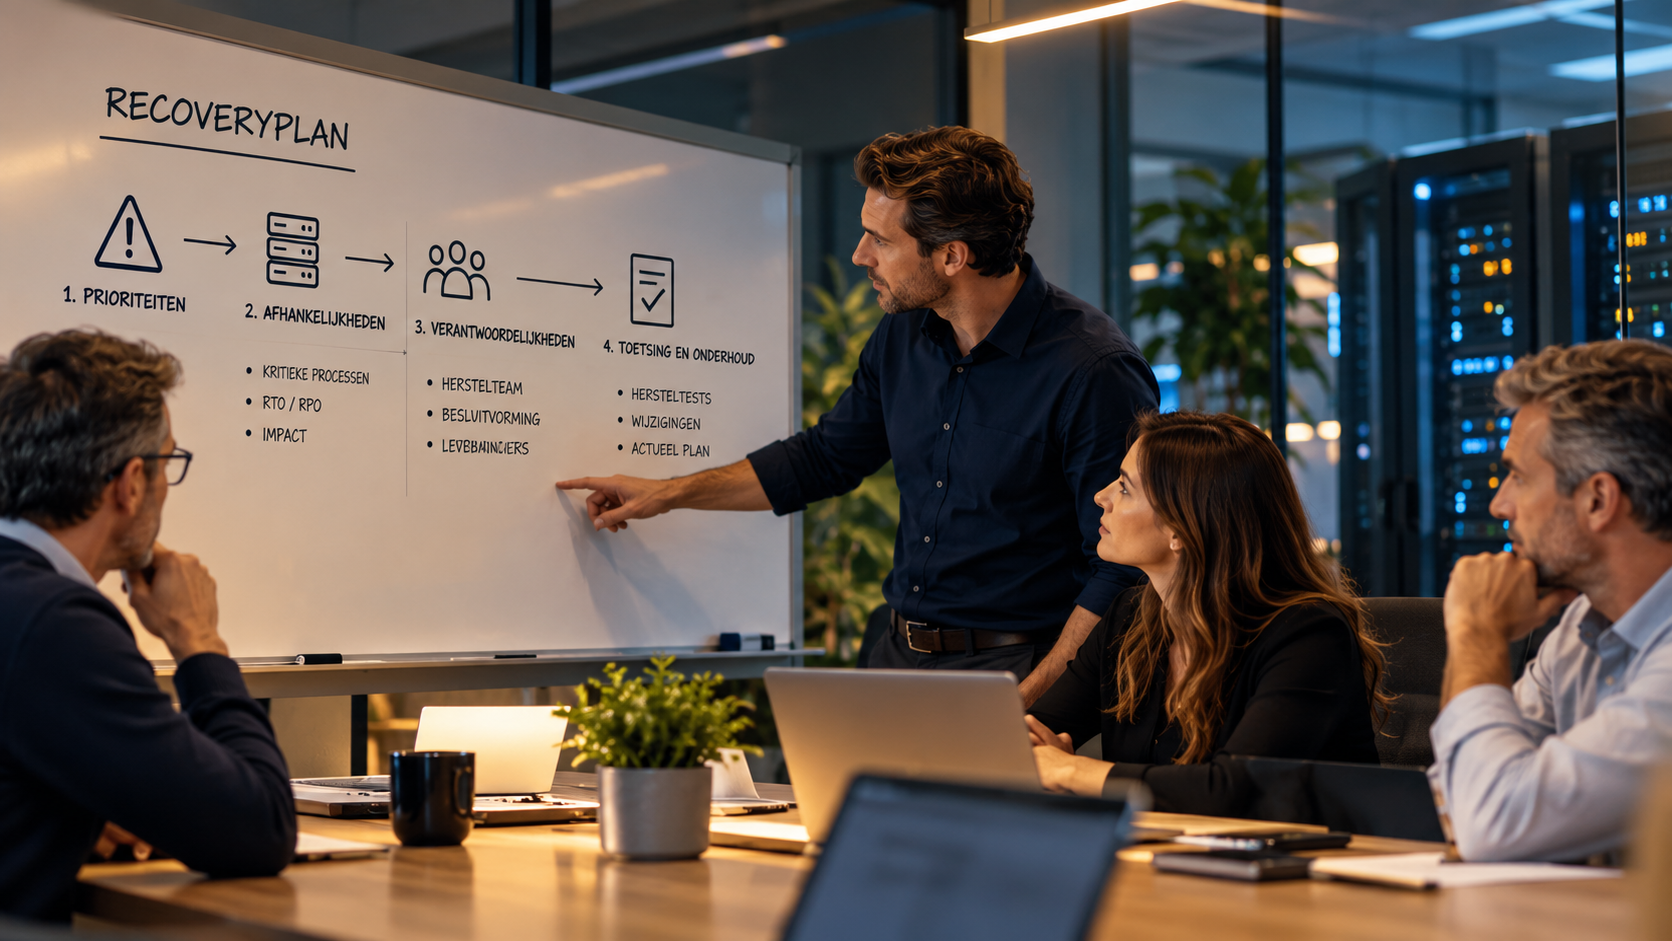
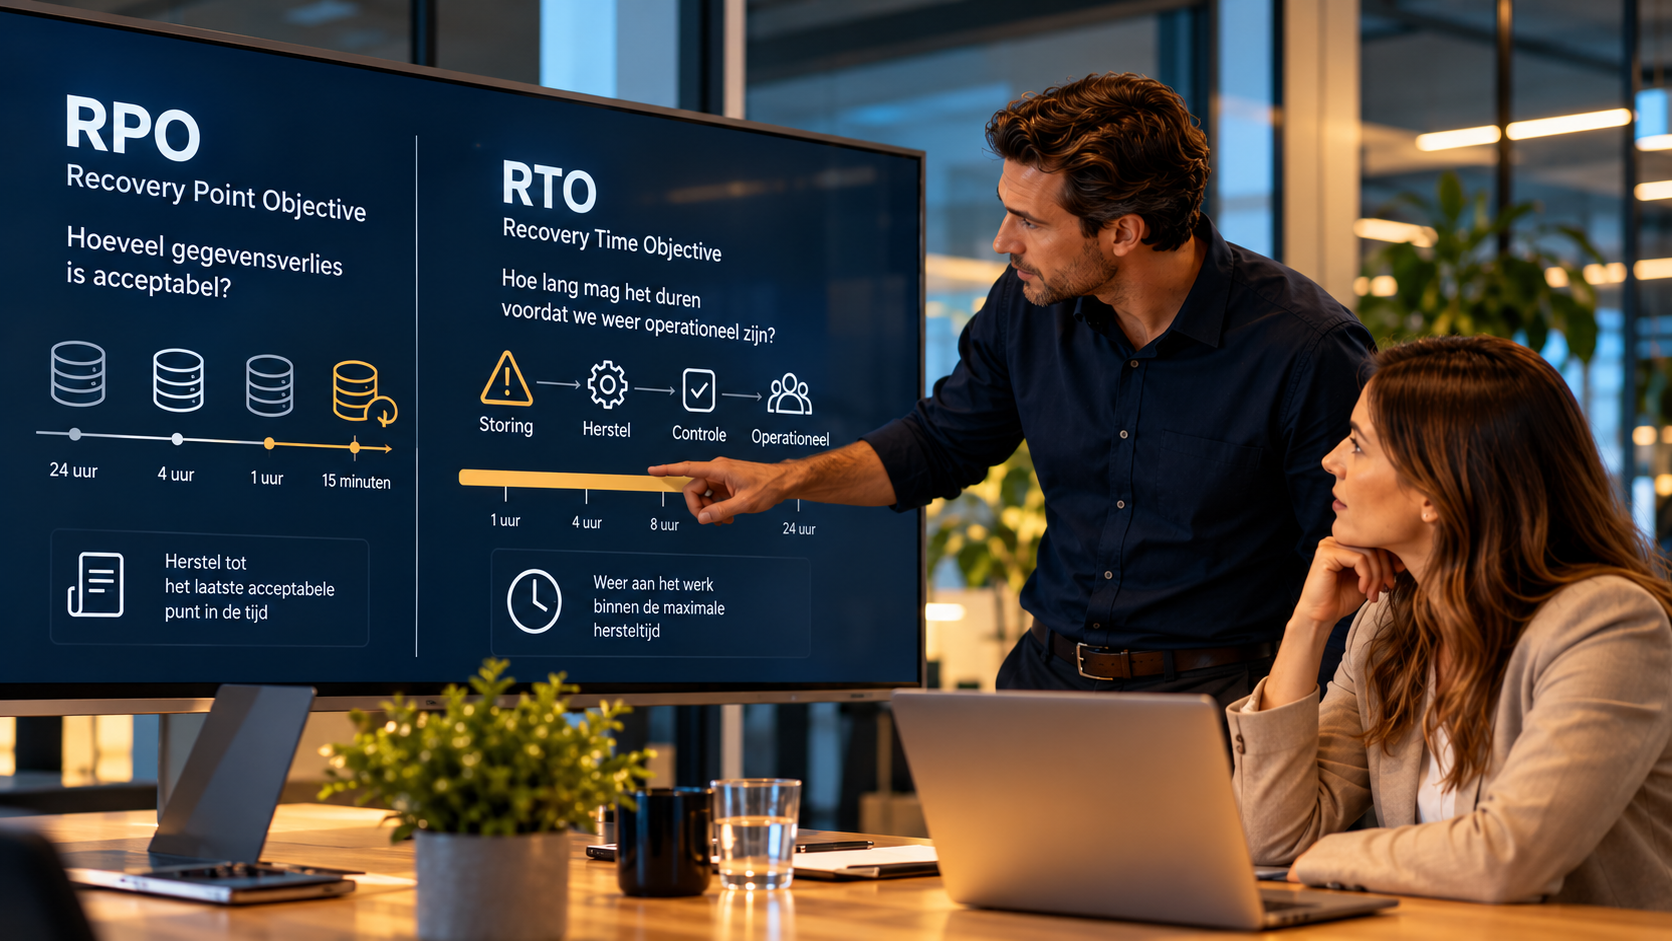
This assessment ties in with the RTO established earlier: the maximum acceptable time within which a system or business process must be recovered. When the standard recovery procedure consistently takes longer than this objective allows, there is a reason to investigate additional recovery provisions.
What makes accelerated recovery possible?
With standard recovery, systems and data are made available again after an incident using a backup or another recovery source. With accelerated recovery, some of the recovery work is prepared in advance, reducing the number of actions needed during an incident.
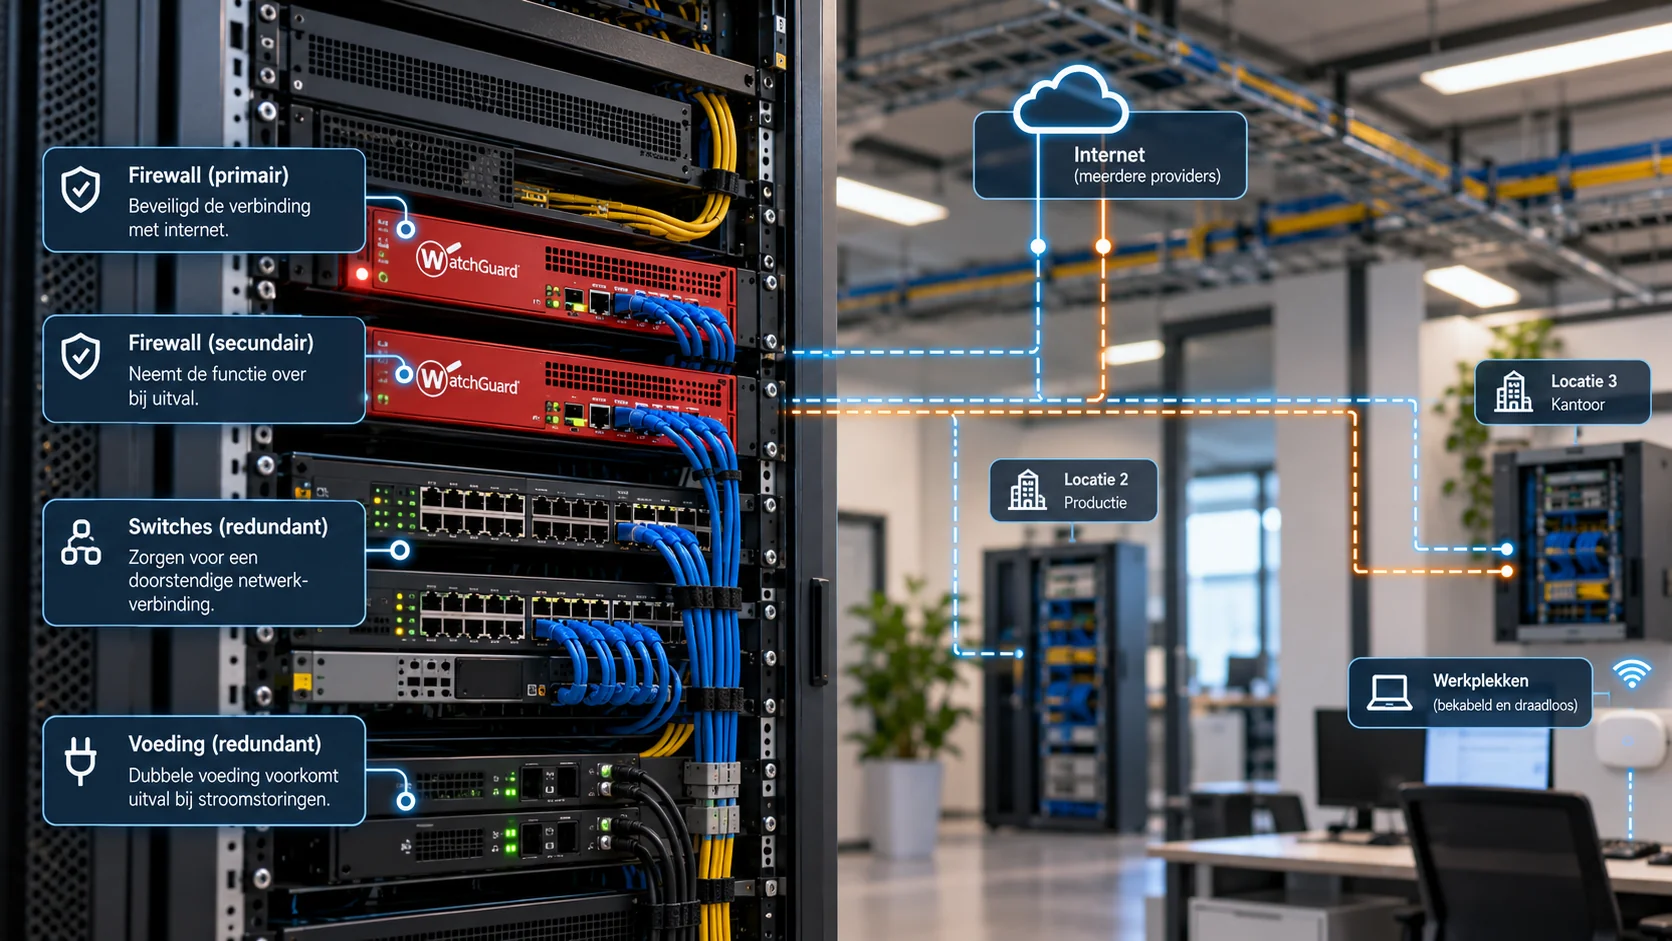
There are various ways to do this. Virtual servers can, for example, be replicated to a second environment so that a recent copy is already available there. A standby system can be set up for critical applications to take over service delivery in the event of a failure. Recovery environments made available in advance, snapshots and automated recovery procedures can also reduce the time required.
The differences between these provisions matter. A snapshot makes it possible to roll back certain changes relatively quickly, but does not necessarily constitute an independent backup. Replication transfers changes to another environment, but can also propagate unwanted changes. A standby system can improve availability, but generally requires additional configuration to ensure that data, connections and applications work correctly.
Failover is the controlled transfer of a service or system to an alternative provision. This can take place automatically or manually. How quickly it works depends on the architecture, data synchronisation and the dependencies of the systems involved.
Accelerated recovery is therefore a combination of technical choices and organisational arrangements, rather than a standalone product. The right configuration depends on the required recovery time, the acceptable amount of data loss and the complexity of the business process.
Being available sooner does not mean being fully recovered
A common pitfall is to assess recovery at the point when a server or virtual machine is running again. For the organisation, however, recovery has only succeeded when employees can resume their work safely and reliably.
An ERP system may be technically available while its database connection is missing. An application server may be running again while users cannot sign in because an identity service is unavailable. Network connections, DNS, certificates, storage systems or integrations with external parties may also be needed before a business process actually works.
Accelerated recovery must therefore account for the full chain of dependencies. Sometimes, restoring one central service matters more than starting dozens of servers at the same time. In other situations, a specific combination of applications, databases and connections must be available before a process can resume.
The security of the recovery environment also needs attention. An alternative environment must not simply become a less secure copy of the production environment. Access rights, network segmentation, logging and administrator accounts must also function responsibly during recovery.
A rapid switch to an environment whose reliability or security has not been sufficiently verified can create new problems. Recovery speed must therefore always be weighed against the assurance that the recovered environment is secure and usable.
What an ERP system outage in a production environment reveals
Consider a manufacturing company that depends on a central ERP system for planning, stock records and production order processing. The application runs on virtual servers and uses a separate database. There are also integrations with a warehouse system and equipment on the production floor.
During a serious failure, the primary server environment becomes unavailable. The company has daily backups, but completely rebuilding the environment and restoring the data is expected to take much of the working day. Production can therefore continue only to a limited extent.
Because the ERP system was previously identified as business-critical, an alternative recovery environment has been set up. The key virtual servers and their data are replicated to this environment according to an agreed schedule. Recovery can therefore begin considerably sooner than if the entire infrastructure had to be rebuilt.
During the switchover, however, it becomes clear that more than the ERP servers is needed. The database, the connection to the warehouse system and several network services must also work correctly. In addition, it must be established whether the available data is sufficiently up to date and reliable to process new production orders.
Thanks to the recovery environment set up in advance and a tested switchover procedure, the company can resume work sooner. The main benefit, however, comes not solely from replication technology, but from having determined in advance which components are necessary, in what order they must be recovered and how their operation will be checked.
Accelerated recovery is particularly valuable when technology and business processes are aligned.
Replication is no substitute for a reliable backup
Replication often plays an important role in accelerated recovery. Copying data and systems to a second environment can greatly reduce the time needed to make an alternative environment available. However, this provision must not be confused with an independent recovery capability.
When data is accidentally deleted, a database becomes corrupted or ransomware encrypts files, those changes can also be transferred to the replicated environment. The second environment may then have the same problems as the original one.
A distinction must therefore be made between making systems available quickly and being able to return to a reliable recovery point. Both matter, but they address different problems.
Where necessary, a sound recovery architecture combines rapid switchover capabilities with backups that are sufficiently protected against unwanted changes or deletion. This includes establishing how far back in time it is possible to go and how the usability of a recovery point is checked.
The security of the alternative environment also deserves attention. If the same administrator accounts provide access to production, replication and backups, a security incident can affect several recovery capabilities at once. A careful design therefore limits interdependencies and protects critical recovery provisions against misuse.
When is investment in accelerated recovery justified?
Not every system needs a second environment or an extensive failover provision. Such measures bring costs for infrastructure, storage, licences, connections, management and periodic testing. They also increase technical complexity, which can introduce new risks in itself.
The decision must therefore be based on the consequences of an outage. A system used for no more than a few hours each month generally justifies a different level of investment from an application needed for a continuous production process. The considerations extend beyond direct financial losses to contractual obligations, reputational damage and the consequences for employees and customers.
It is useful to assess different recovery options side by side. Sometimes, an improved backup provision combined with a recovery procedure set up in advance can already save enough time. In other situations, replication to an alternative location is necessary. For processes where virtually no interruption is acceptable, an architecture with redundant systems or systems that are already active and available may be appropriate.
The most expensive solution is not automatically the best. What matters is a proportionate provision that meets the organisation's actual continuity needs.
The availability of people and suppliers must also be taken into account. A technically advanced recovery environment offers little benefit if a necessary specialist cannot be reached or if the switchover depends on actions that are insufficiently documented.
Accelerated recovery must demonstrably work
A recovery environment set up in advance only provides assurance when its operation is checked regularly. This means establishing not only whether replication is successful, but also whether the alternative environment can actually be used to resume the required business processes.
During a recovery test, the necessary systems are made available in the correct order and checks establish whether applications, data, connections and user permissions work. The measured recovery time can then be compared with the agreed RTO. The test must also clarify how much data could be lost and whether this is within the agreed RPO.
Particular attention is needed for the return to the original environment (failback). Following a temporary switchover, systems and data may need to be synchronised again before normal operations can be restored. This process can also cause risks and interruptions. A recovery strategy is therefore incomplete if only the initial switchover has been prepared.
The organisation must also know who is authorised to initiate failover, which checks are needed beforehand and when business operations may start using a recovered environment again. These responsibilities belong in the recovery procedures and must be assessed during tests.
Recovery speed is a deliberate choice
Accelerated recovery can significantly reduce the consequences of serious IT disruptions. Making critical systems available in an alternative environment in advance, automating recovery actions and thoroughly mapping dependencies can shorten the time until work resumes.
But the value of these provisions is not determined by how quickly a server restarts. What matters is whether the business-critical process can resume safely and reliably within the required time.
Malenco therefore approaches accelerated recovery as part of responsible IT management. We consider the relationship between business processes, recovery objectives, infrastructure, security and practical feasibility. We assess which additional provisions are worthwhile and how their operation can be demonstrated.
Not every system needs to be available immediately. For systems where prolonged downtime is unacceptable, however, recovery must be prepared in advance and proven in practice.