An internet connection goes down, a switch develops a fault or a server unexpectedly stops working. In a well-designed IT environment, a failure like this need not immediately affect business operations. An alternative can take over the function, allowing employees and business processes to continue as far as possible. That sounds straightforward, but in practice, building a reliable infrastructure involves more than simply duplicating equipment.
Two internet connections, for example, do not automatically provide assurance if they follow the same physical route. Two servers cannot help each other if they depend on the same faulty storage system. And a second firewall has little value if the switchover has not been configured properly. Redundancy is therefore not solely about having spare equipment available, but above all about identifying and reducing vulnerable dependencies. The aim is to prevent a failure in one component from unnecessarily bringing an entire business process to a halt.
Availability starts with the consequences of an outage
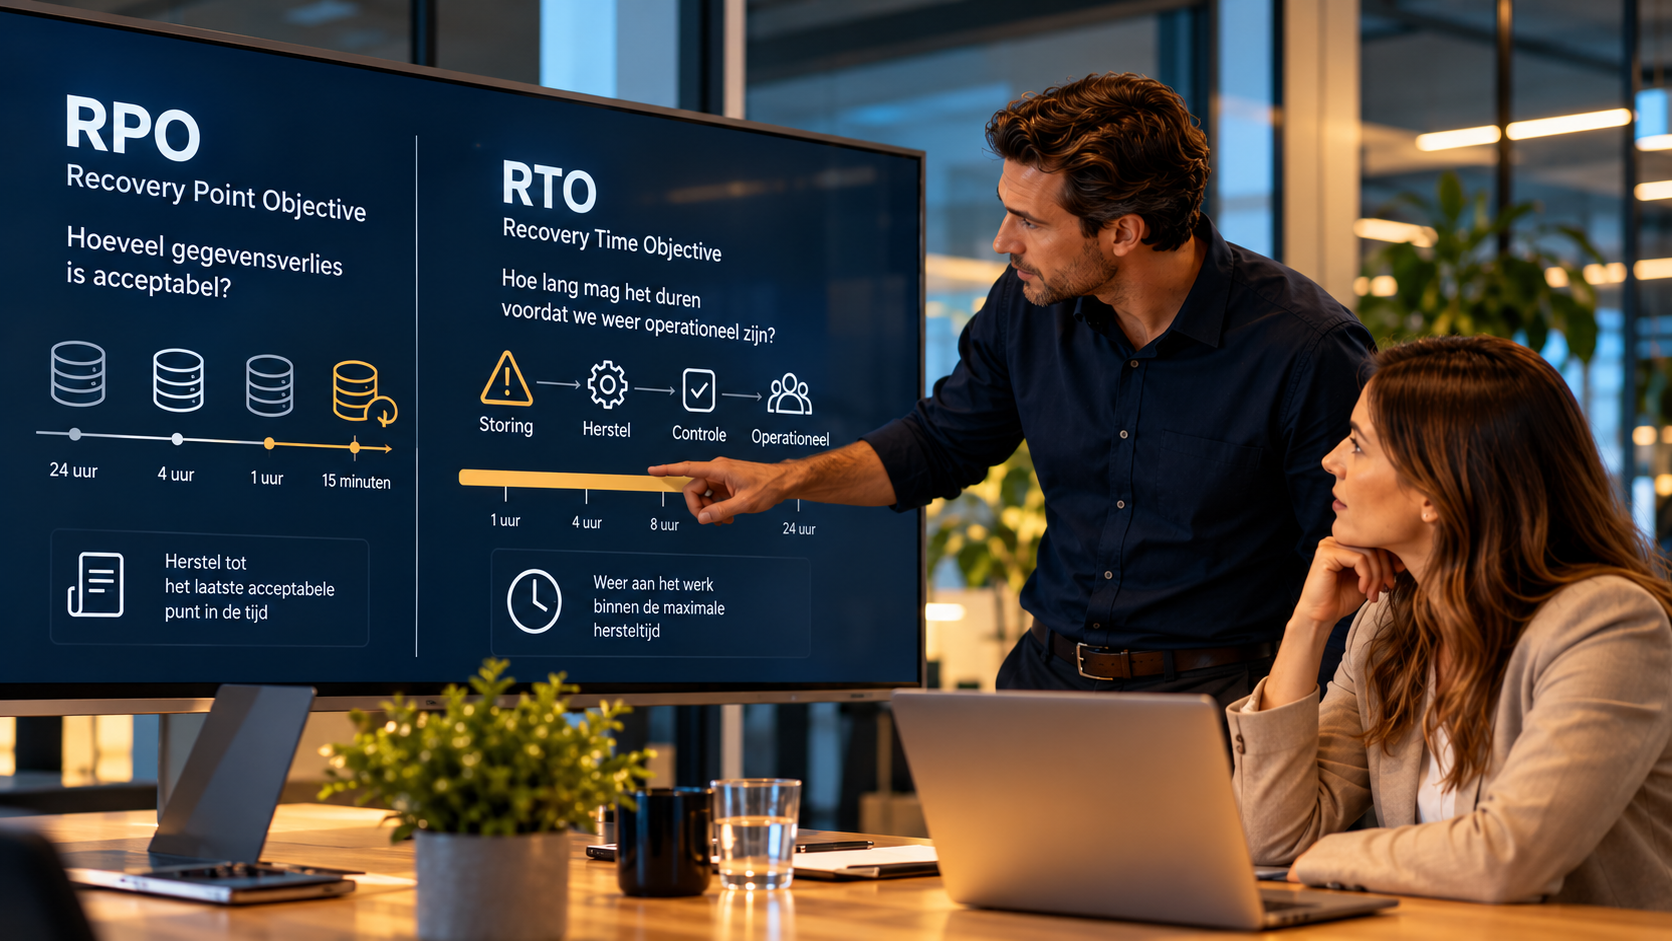
Not every IT service needs to be available at all times. If an internal reporting environment is inaccessible for an hour, that may be inconvenient without immediately bringing work to a standstill. For a production system, a logistics application or an entire company's internet connection, the same outage can have far greater consequences. A sound availability strategy therefore starts with the question of which business processes depend on which IT services, rather than with the choice of equipment.
Which systems are essential for processing orders? What happens when employees can no longer access their applications? How long can a production process continue without a connection to the central system? And which services must remain immediately available, even when a component fails? The answers to these questions determine where redundancy is necessary, which form is appropriate and how much interruption the organisation can accept. An environment in which a few minutes of downtime is acceptable has different requirements from a process that needs to continue with virtually no interruption.
Redundancy, failover and availability are not the same thing
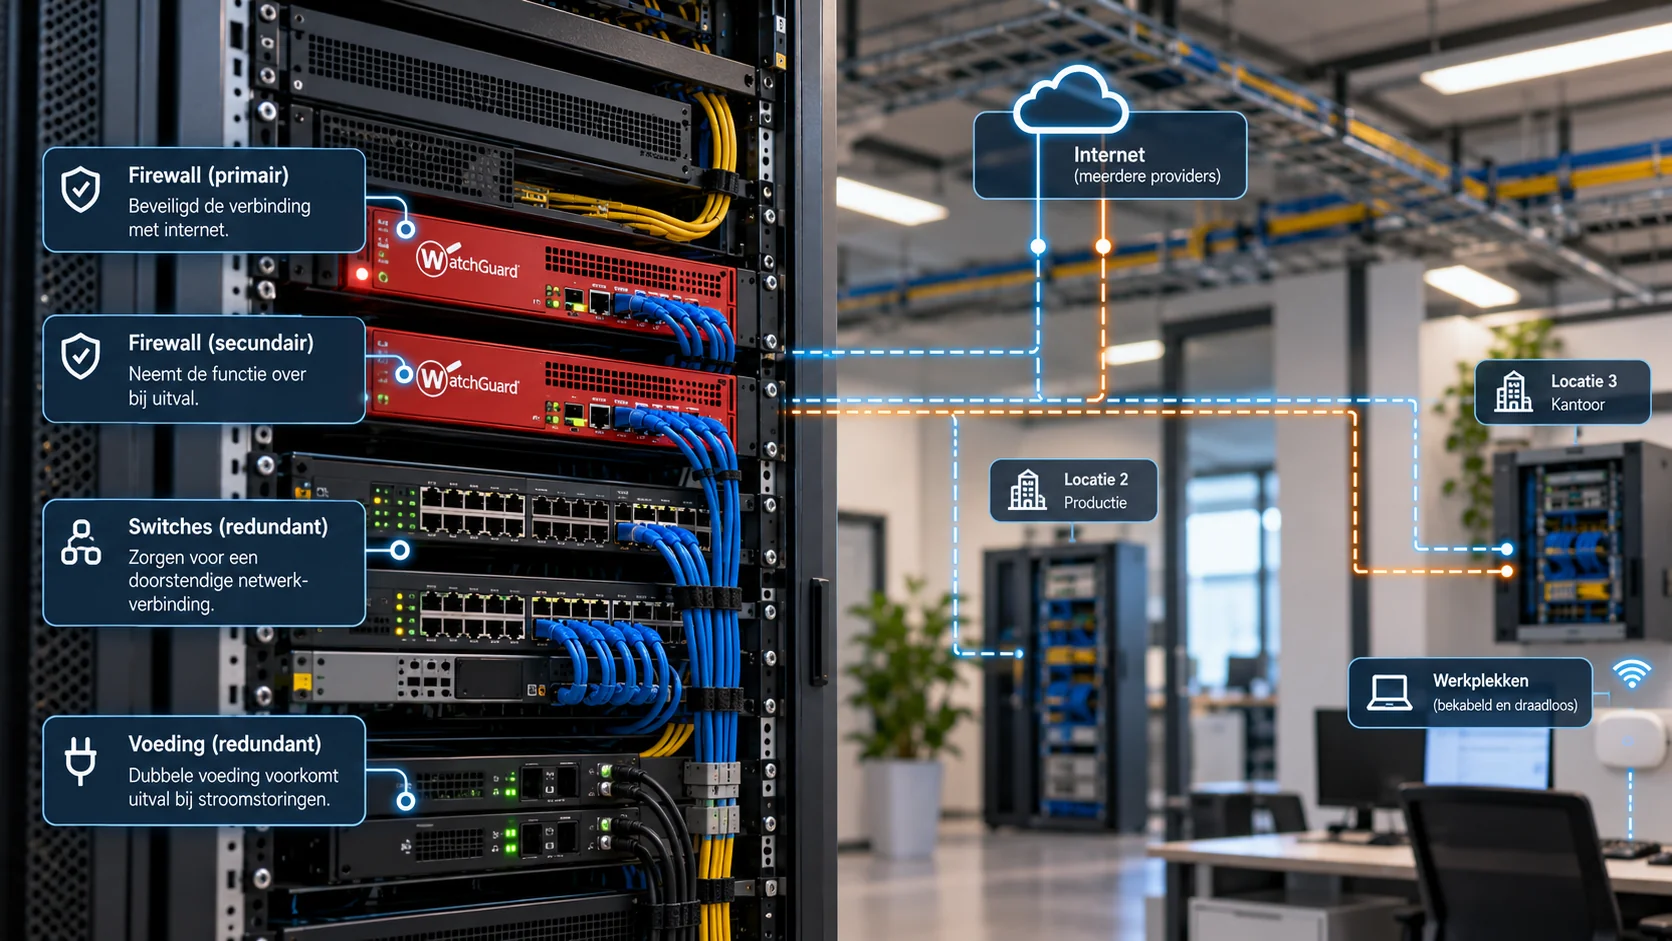
Although these terms are often mentioned together, they describe different aspects of a reliable IT infrastructure. With redundancy, a critical function is designed so that an alternative is available. This often involves duplicating equipment, for example with two switches, two firewalls, multiple servers or a second internet connection. Separate network paths, multiple power supplies and redundant storage can also form part of this. The principle is that the failure of one component should not automatically result in the loss of the function that component performs.
Failover is the mechanism by which the alternative takes over the function of the primary system or connection. This can happen automatically, for example when a firewall cluster detects a faulty device, but in other situations manual intervention may be needed. How quickly and reliably that takeover occurs is at least as important as having the standby system or connection available. An organisation can therefore have redundant equipment without a failure being handled automatically or without a noticeable interruption.
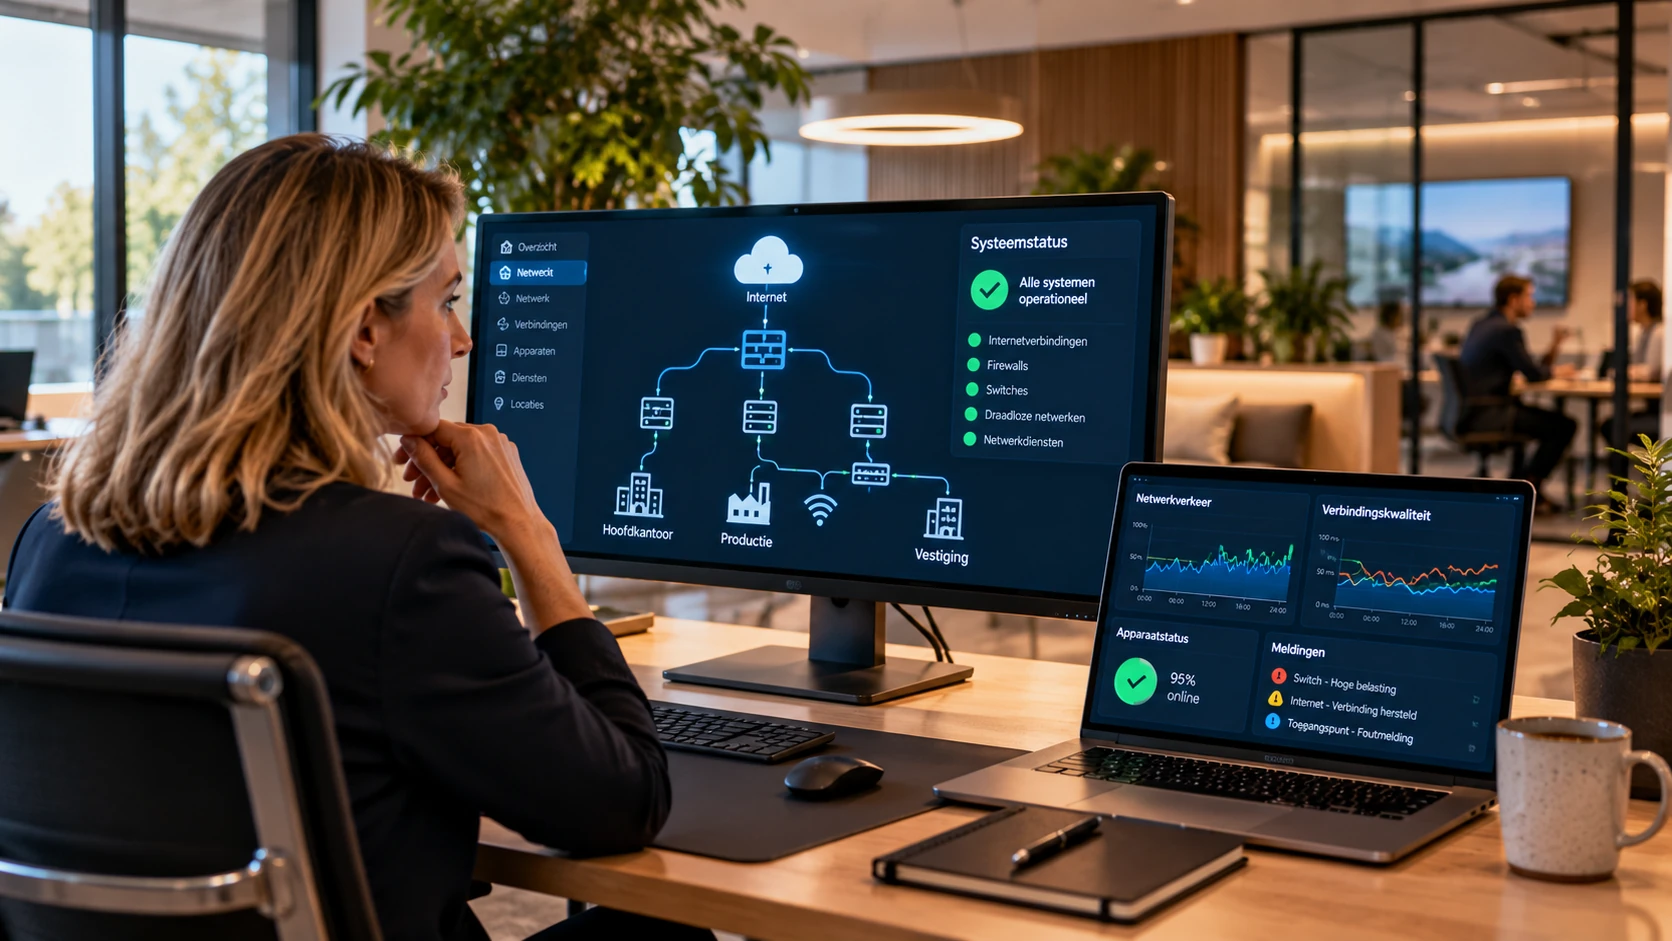
Ultimately, the issue is availability: can employees and business processes continue to function? A second internet connection may become active successfully while existing sessions are still disconnected. An application may start on another server, but only become fully usable again after some time. A system may also be technically accessible while a necessary connection to another system is missing. The effectiveness of redundancy must therefore be assessed across the complete service, rather than solely by the status of individual devices.
Redundancy requires more than duplicating equipment
Duplicate equipment is an important means of handling failures, but a redundant design is only effective when the dependencies surrounding that equipment are also taken into account. A network may, for example, have two central switches that can take over each other's function. If both switches are connected to the same electrical circuit, however, a single power failure can still bring down the entire network. The switches are duplicated, but their power supply remains a point of vulnerability.
The same applies to two internet connections that enter the building along the same cable route. Despite having two providers, a single instance of cable damage can interrupt both connections. Such dependencies also occur in server environments. Two servers may be able to take over each other's tasks, but if both depend on a single storage system, a failure of that storage can still affect the entire service. The design must therefore account not only for individual devices, but also for the connections, power supplies and other services and infrastructure on which they depend.
Not all risks are physical, either. Two firewalls in a high-availability configuration can provide excellent protection against the failure of one device. If an incorrect configuration is distributed to both firewalls, however, the same error can affect both devices. In that case, redundancy protects against certain hardware failures, but not necessarily against configuration errors. The relevant question is therefore not just whether a component is duplicated, but above all which failures can affect both alternatives at the same time.
How does failover work in practice?
When a primary system or connection fails, the infrastructure needs to recognise the failure and determine whether the alternative should take over the function. What happens next varies according to the environment and the technology. In some systems, switchover is fully automatic, while in others an administrator needs to intervene. Broadly speaking, four phases can be distinguished.
Detecting the failure.
The system establishes that the primary system or connection is no longer functioning properly. It is important to check not only whether a device is still powered on, but also whether the required service is actually working.Switching to the alternative.
The alternative takes over the function. Depending on the configuration, this may happen automatically or require action by an administrator. Existing connections may be temporarily interrupted during the switchover.Checking operation.
After the takeover, it must be established whether the services and applications involved are actually functioning. A successful technical switchover does not automatically mean that employees can continue working without problems.Returning to normal operation.
Once the original system or connection has been restored, a decision is made on whether and when it is sensible to switch back. This need not happen immediately or automatically. Sometimes a planned switchback actually prevents a second disruption.
These phases are not a universal technical procedure, but show that reliable failover does not end with activating a standby system or connection. Checks, recovery and management are also part of the process. Switching back deserves particular attention, because returning too quickly to a primary system or connection that is still unstable can cause further interruptions.
Automatic switchover is not always necessary
Redundancy is often associated with systems that switch over without human intervention. This may be necessary for business-critical services, but not every service requires the same approach. A brief interruption of a few seconds can already be problematic for certain applications, while other systems may be unavailable for several minutes or longer without major consequences. The desired availability must therefore be aligned with the business process being supported.
Automatic failover can greatly reduce recovery time, but also requires careful configuration and checks. For example, a system must prevent repeated switching between two connections when one is unstable. In other situations, a controlled manual switchover may be appropriate, for example when an alternative environment needs to be checked first or when the consequences of an incorrect switchover are greater than those of a brief interruption. The point is not to make every service switch over as quickly as possible, but to ensure that the chosen approach fits the organisation's risks and continuity requirements.
A redundant infrastructure also needs to be tested
A redundant system or connection that is never tested provides less assurance than it appears to on paper. Equipment may function without problems for years while a dependency that obstructs switchover develops unnoticed. A configuration change may cause a second connection to stop working properly, while an alternative server may be available but lack all the settings needed to take over an application. Such problems sometimes only become apparent when the primary system or connection actually fails.
Testing redundancy should therefore be part of routine IT management. This does not mean that every system or connection must constantly be deliberately switched off, but it does mean periodically establishing whether the alternative route, system or connection is available, whether switchover works as intended and whether the services involved remain usable afterwards. Changes also deserve attention. Adding a new application, network connection or dependency can affect the existing redundant configuration. An availability design remains reliable only if it evolves with the IT environment and its operation is checked regularly.
Which components need redundancy?
It is technically possible to duplicate many components of an infrastructure, but that does not mean doing so is sensible or necessary for every organisation. Redundancy incurs costs, both in purchasing and in management. Additional complexity can also introduce new risks if the configuration is not managed adequately. The decision must therefore be based on the importance of the service, the consequences of an outage and the time within which service delivery needs to resume.
For an organisation that depends almost entirely on cloud applications, the internet connection can be particularly critical. In a production environment, it may instead be the connections between machines, control systems and central applications that determine continuity. Requirements can also vary considerably within a single organisation. Some business processes require an almost immediate takeover, while for others controlled recovery within an agreed period is sufficient. The principle is to align availability with what the organisation actually needs, rather than applying the same degree of redundancy everywhere.
Redundancy is part of a broader approach to continuity
Redundancy helps to handle certain failures, but is no substitute for backup and recovery. If a server fails, a second server can take over service delivery. But if data is deleted, corrupted or encrypted by ransomware, the same damage may also occur on the alternative system. Other measures are needed to address this, such as appropriate backups, recovery procedures and the ability to return systems and data to a trustworthy state.
A sound approach to continuity therefore combines different measures. Redundancy limits the consequences of component failures, failover handles the takeover when needed, and backup and recovery make it possible to return to a usable state when availability alone does not provide sufficient protection. These measures complement each other, but each has its own function. Designing them together creates an infrastructure that can withstand equipment failures and is also prepared for other disruptions to business operations.
Reliable IT requires an understanding of dependencies
The value of redundancy only becomes clear when it is understood which systems, connections and services depend on each other and what happens when one of them fails. This requires more than an inventory of equipment. It requires an understanding of network connections, power supplies, applications, storage, external services and the way business processes use them. That understanding provides the basis for deciding where an alternative is necessary, how switchover should work and which checks are needed to keep it reliable.
A sound redundant design is therefore not a collection of duplicate devices, but a deliberate design of the IT infrastructure around the organisation's continuity. The aim is not to duplicate as much equipment as possible, but to ensure that a failure in one component does not unnecessarily bring the organisation to a standstill.